Post-training case study: Reaching frontier-level intelligence on global payroll with Deel
This post is authored by Eran Goldstein, Asaf Karnieli, Shaked Meirom and Joanna Kramer, in collaboration with Deel’s Abhijit Mehta and Anthony Li.
Building a global payroll model that is available to reliably and truthfully answer employee questions across the world, each navigating highly individualized employment terms and local regulatory landscapes, is not a simple task.
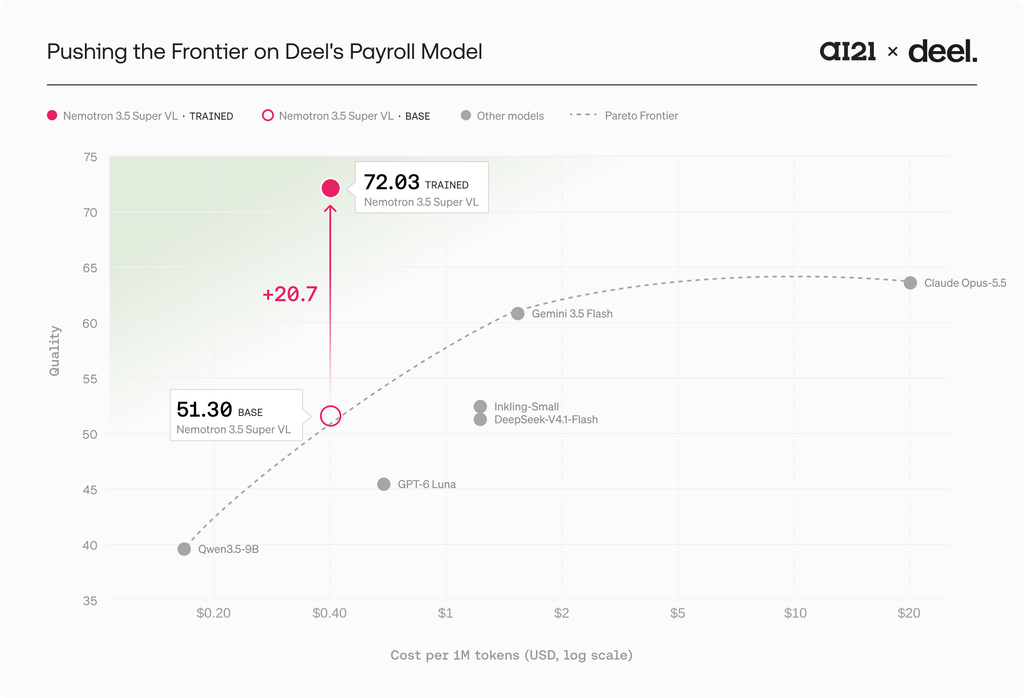
Yet, over the course of a three-week engagement, AI21’s Forward-Deployed Researchers (FDRs) worked with the team at Emet, Deel’s AI lab for model evaluation and training, to post-train recently released NVIDIA Nemotron 3.5 Super VL, delivering a model that surpasses the frontier at a fraction of the cost:
- 20.7-point quality improvement over the base model
- 8-point quality improvement over Claude Opus 5.5
- 50x cheaper model than Opus 5.5 (as measured in cost per 1M tokens)
Achieving those results was possible due to the expert criteria and benchmark built by Emet by Deel, whose in-country payroll specialists defined what a complete answer contains, as well as the AI21 FDR team’s sequentially training the model with SFT and then SDPO (self distillation policy optimization). This post details the methodology behind these results.
Why global payroll questions are challenging for models
The domain
Deel, the global HR and payroll platform, supports more than 45,000 companies across 150+ countries, answering payroll questions that span multiple countries and jurisdictions. What constitutes the right answer depends on local tax rules, employment contracts and company policies – and all three change regularly. A typical question, usually about 20 words long, might be: “As an EOR employee in France: We have an employee in France who started maternity leave on 14 August. My understanding was that CPAM would fund this. How does the funding and the employer’s part work?”
In addition to getting the answer right, the model also needs to phrase it according to Deel’s terminology, policies and style.
To grade the model’s answers, we relied on EmBench Payroll, Emet’s public payroll benchmark. Each question has 3–6 rubric assertions. Some are factual (“states the daily cap for the CPAM allowance is 101.94 euros”), while others check what the answer covers or how it frames the situation. Answers are graded on two metrics, with GPT-6 Sol as the LLM Judge:
- Criteria met: the average share of a question’s assertions that the answer satisfies
- All criteria met: the share of questions where every assertion is satisfied
While frontier models handle the domain well – for example, Opus 5.5 meets 64.0% of the criteria and fully answers 26.3% of the dev questions – they are also expensive. In contrast, open models are significantly cheaper, but generally start with lower quality – the base version of Nemotron 3.5 Super scores at just 51.3%.
Deel was looking for an open model that gives the complete answer unprompted, at a fraction of frontier cost. Post-training makes it possible to reach that desired cost-quality operating point.
Methodology
Where the base model falls short
We started by evaluating base Nemotron 3.5 Super and conducting error analysis on its rollouts. Most failed rollouts were incomplete rather than wrong. For example, they hedged where the law is definite, gave no concrete figures, or skipped framing facts and mixed up related concepts. Those patterns suggested the model mostly had the requisite knowledge – but needed to be steered towards a complete answer.
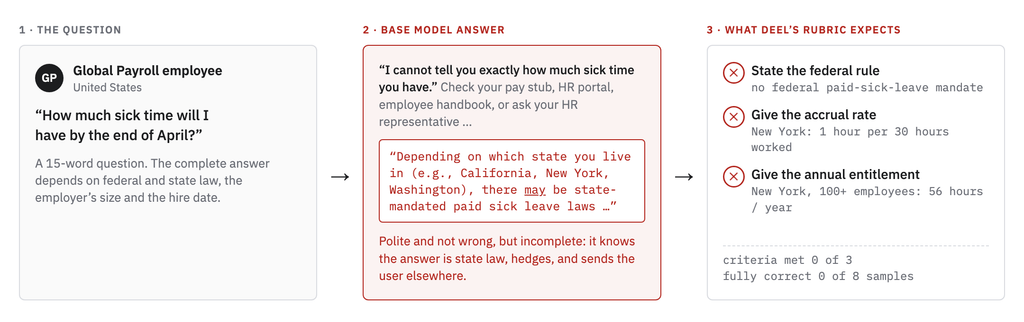
The figure below (Figure 2) shows a typical example. When a U.S. employee asked how much sick time they would have by the end of April, the base model recognized that the answer depends on state law, yet hedged and referred the user to HR instead of stating the rule and the relevant figures. As a result, the answer met none of the three rubric criteria, and none of eight sampled answers to this question was fully correct.
Training the behavior into the weights
Step 1: Near-policy SFT
To improve the model while avoiding catastrophic forgetting, we kept training as on-policy as possible. That meant learning from the model’s own rollouts rather than from answers written by another model, since data close to the policy’s own distribution is easier to learn and causes less forgetting [3]. However, the base model rarely produced rollouts good enough to learn from. It fully answered only 10% of the dev questions.
To raise the quality of its rollouts without leaving its distribution (training ‘near-policy’), we provided the model with hints during generation. We refined the hints iteratively through error analysis. They covered the model’s role and what the task expects of it, the level of detail a payroll answer needs, Deel’s terminology and answer structure, and the distinctions users tend to blur. The hints added no new domain knowledge. They only steered the model toward using what it already knew.
We then sampled hint-guided rollouts from Nemotron 3.5 Super with reasoning turned on. We kept only the rollouts that met every rubric assertion, including their reasoning traces, and these formed our curated training set: just 412 examples, small by post-training standards. Finally, we trained the model with SFT on this set, with the hints withheld.
Near-policy SFT lifted performance on the dev set from 0.513 / 0.100 to 0.657 / 0.229 (criteria met / all criteria met).
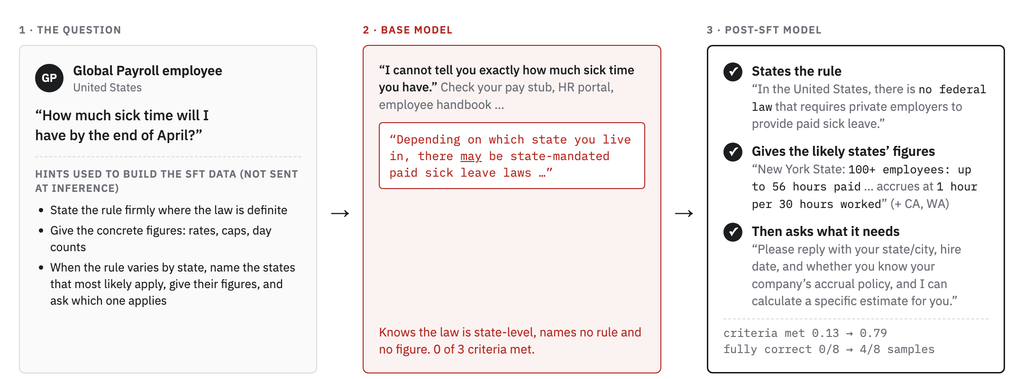
Revisiting the sick-leave question shows the effect of this step. As can be seen in the figure below, the trained model states the federal rule, gives the figures for the states most likely to apply, and asks for the details it needs, raising criteria met on this question from 0.13 to 0.79.
Step 2: SDPO with a privileged teacher
Once we had established a stronger checkpoint with SFT, we turned to SDPO (self-distillation policy optimization) [1,2], a recent on-policy method that trains the model using self-distillation. The student (trained model) answers the plain question, and a teacher – the same model with access to privileged information for each question – then scores the student’s own tokens.
The information we gave the teacher remained the same as the injected hints above.
However, SDPO has advantages beyond training with SFT. First, SDPO is an on-policy training method, i.e., rollouts are generated by the most recent policy model. In addition, this method is a fine-grained approach to steer the student’s behavior by rewarding desired response characteristics (and penalizing undesired ones), instead of relying on the model to infer those characteristics from demonstrations alone.
As a result of training with SDPO, the model’s performance highly improved:
- When training the base model using SDPO directly: dev-set results rose from 0.513 / 0.100 to 0.638 / 0.183, close to the SFT-trained scores (0.657 / 0.229) without any curated data.
- When starting SDPO from the SFT checkpoint (SFT → SDPO): produced our best Nemotron 3.5 Super results: 0.720 / 0.339.
Notably, we reached these results with a small training set: 412 questions for SFT and 698 for SDPO, a superset of the SFT questions. This was possible because we kept both steps as close to on-policy as we could. In SFT, we trained on the model’s own hint-guided completions, so the curated training set stayed close to the model’s own distribution. In SDPO, training is fully on-policy: each pass over a question produces fresh rollouts from the current policy, and with them new training signal, rather than a fixed target the model could memorize. SDPO also needs no gold answer, so it could learn from the questions the model still got wrong. This shows that post-training a model for a specific task can be done effectively with a small dataset.
This case study offers an excellent example of a self-distillation pipeline. Similar to GRPO, where we rely on the student’s capabilities to bootstrap the performance and create a flywheel, SDPO does the same. The flip side is that on-policy training can only amplify what the student already produces: when the base model rarely produces good answers on its own, there is little signal to learn from. It is therefore standard practice to first distill from a teacher, or otherwise improve the base model, before on-policy training begins. Our work with Deel illustrates a situation where off-policy distillation from a self-teacher, the model itself guided by hints, works well as a precursor to SDPO, such that the combination of both methods improves over each of them separately.
Results
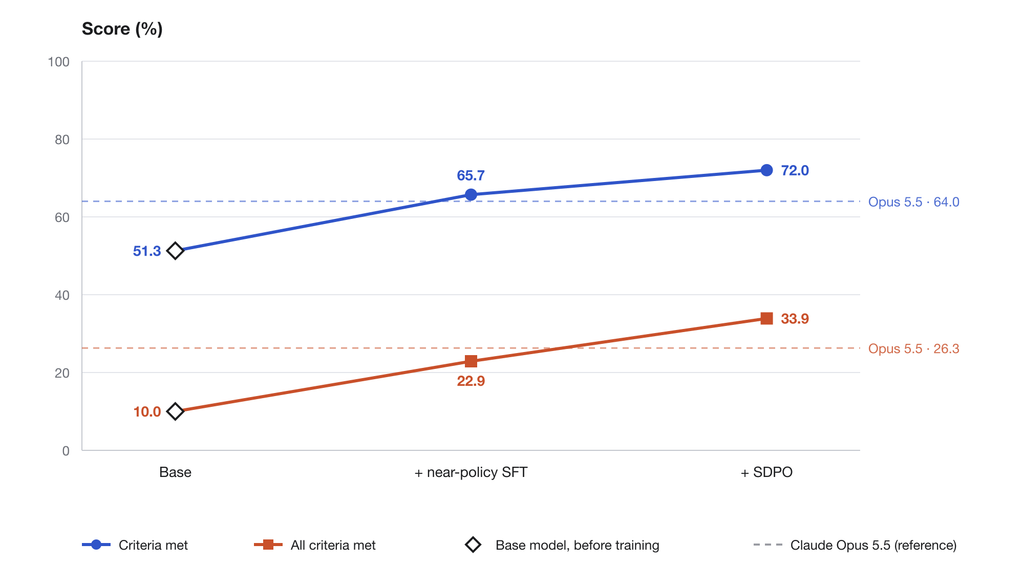
The sequential usage of SFT, followed by SDPO, produced our strongest model on both metrics, surpassing Claude-Opus-5.5 by ~8 points.
Reaching frontier-level quality with SFT and SDPO
By implementing a sequential training process that utilized both SFT and SDPO, AI21’s FDR team improved Nemotron 3.5 Super’s performance on Deel’s global payroll task by 20.7 points compared to the base model, and by 8 points compared to Claude Opus 5.5.
Working in a domain as complex as global payroll, where a right answer is defined both factually and stylistically, AI21’s FDR team utilized near-policy SFT followed by SDPO to steer the model’s behavior and highly improved the quality.
Together, AI21 and Deel demonstrated that, equipped with the right data and training recipe, companies don’t need to choose between a frontier models’ quality and an open models’ price. By post-training Nemotron 3.5 Super VL, Deel can now power its global payroll with a model that surpasses Claude Opus 5.5 on quality, while costing 50x less.
Read more about the project on Deel’s blog.
References
- Siyan Zhao, Zhihui Xie, Mengchen Liu, Jing Huang, Guan Pang, Feiyu Chen, Aditya Grover. Self-Distilled Reasoner: On-Policy Self-Distillation for Large Language Models. arXiv:2601.18734, 2026.
- Jonas Hübotter, Frederike Lübeck, Lejs Behric, Anton Baumann, Marco Bagatella, Daniel Marta, Ido Hakimi, Idan Shenfeld, Thomas Kleine Buening, Carlos Guestrin, Andreas Krause. Reinforcement Learning via Self-Distillation. arXiv:2601.20802, 2026.
- Zhaorui Yang, Tianyu Pang, Haozhe Feng, Han Wang, Wei Chen, Minfeng Zhu, Qian Liu. Self-Distillation Bridges Distribution Gap in Language Model Fine-Tuning. ACL 2024, arXiv:2402.13669.